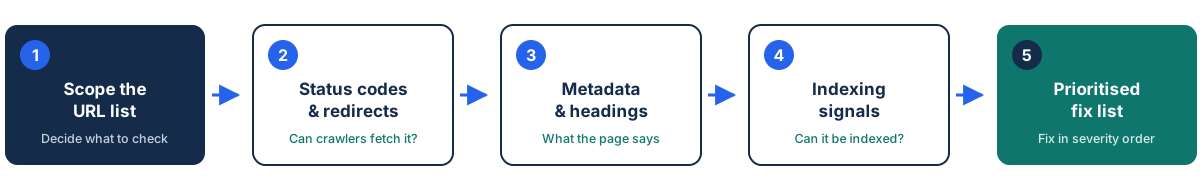
A website SEO audit is a structured check of whether search engines can fetch, index, and understand your pages. You do not need paid software to run a useful one. Work in this order: confirm each URL returns the right status code without long redirect chains; check the title, description, headings, and canonical tag on the page itself; verify nothing blocks indexing; and finish with internal links, robots.txt, and the sitemap. Record every problem, with its URL and evidence, in one severity-sorted list. The worked example in Step 3 is a real one: an audit of this site's own previous build, run in October 2026 immediately before that build was replaced.
Step 1: Define the scope and build your URL list
An audit fails when it tries to check everything at once. Start by deciding what you are auditing:
- List the pages that matter. Start from your sitemap, your analytics landing pages, and any URLs that earn money or leads. A small site may mean 20 URLs; a large one, every template type plus a sample of each.
- Write down the expected result for each URL. Its intended status code (usually 200), its preferred URL form (HTTPS, with or without
www), and its topic. You cannot spot a wrong redirect if you never decided what "right" looks like. - Pick your tools. You need a browser, a terminal for
curl, and a page checker. Our free SEO Checker fetches a URL the way a crawler does and reports status, redirects, metadata, headings, canonicals, and indexing signals in one pass.
Keep the audit in one document: URL, check, result, severity, planned fix. It becomes your fix list in Step 7.
Step 2: Check status codes and redirects first
Before reading any content, confirm the URL actually delivers a page: a 404, a server error, or a redirect chain makes every later check pointless.
Run a header check in your terminal:
curl -sI https://atoztools.pro/Here is that response, trimmed to the lines an audit uses:
HTTP/1.1 200 OK
Date: Fri, 23 Oct 2026 20:23:53 GMT
Content-Type: text/html; charset=UTF-8
Server: hcdn
The status line tells you the outcome: 200 means the page was served, 301 or 302 means you were redirected (the Location header shows where to), 404 means not found, and 5xx means a server error. Record the final status for every URL. Then count the redirects it took to get there. One is normal — HTTP to HTTPS, for example. Two or more in a row is a chain; shorten chains so the first redirect points straight at the final URL. If you find chains or pages bouncing between two URLs, fix them with the method in How to Fix Redirect Chains and Redirect Loops before you continue.
Also request the HTTP version of each key URL: it should redirect to HTTPS, not serve a second copy of the page. The old build in our worked example passed this test — http://atoztools.pro/ returned a clean 301 to HTTPS — proof a site can pass one check and still fail the audit.
Step 3: Worked example — auditing our own previous build
To show what a real audit finds, we audited the previous build of this site in October 2026, immediately before its rebuild. It looked finished, but its database had never been populated, so underneath the designed homepage, categories and testimonials it served an empty shell. We fetched the key URLs with curl and recorded what came back:
| Check | Result on the previous build of atoztools.pro |
|---|---|
| Homepage status | 200 OK, 21,755 bytes |
| Tools on the homepage | None — "0 free tools" appears three times, the counters read "0 Free Tools / 0 In-depth Guides", and no tool page is linked anywhere |
| Testimonials | A "Loved worldwide" section shows named five-star reviews praising tools that do not exist |
Tools index (/tools/) |
403 Forbidden — a generic server error page, 787 bytes |
| Legal pages | Privacy policy, terms, disclaimer and about all return 404 |
| XML sitemap | Returns 200 listing 14 URLs — but 12 return 404; only the homepage and contact page are live |
| ads.txt | 404 — the body is the plain text "No ads.txt configured." |
| robots.txt | Present and permissive: allows all crawling and names the sitemap |
| Title, description, H1, canonical | All present and reasonable — the failure was availability and content, not metadata |
The high-priority findings stop the site working at all: a sitemap sending crawlers to 12 dead URLs, a 403 on the tools index, legal pages returning 404, and a homepage answering 200 while containing nothing. Medium: testimonials that read as fabricated social proof, and the missing ads.txt, which matters once advertising runs. Low: the canonical omits the trailing slash every other reference to the homepage uses.
Notice what is not on the list. The robots.txt file was present and correct — but had it been missing, that would not have been an issue at all: with no robots.txt, crawlers may fetch everything, the normal default. The sitemap existed too, yet its inaccuracy, not its existence, did the damage; and on a small site, having no sitemap is at most a minor note, because search engines find small sites by following links. Severity comes from consequences, not from whether a file exists.
Step 4: Check titles, descriptions, and headings
With status confirmed, audit what the page says about itself:
- Title. Every page needs one, unique across the site, describing the page. Search engines truncate titles by pixel width, not by character count — there is no character-count rule and no penalty for a long title. The commonly quoted 50–60 characters is only a practical guideline for what usually fits on one line. A very short title wastes an opportunity — not a violation.
- Meta description. Not a ranking signal, but it is the text search engines most often use for the snippet under your title. The 120–160 character range is likewise a display guideline, not a rule. Without one, the search engine improvises a snippet from your content.
- Headings. One H1 stating the page topic, then H2 and H3 subheadings in logical order. Multiple H1s, skipped levels, or keyword-stuffed headings make the page harder to parse — and a page can have no H1 at all, which is easy to miss if you only look at the rendered page.
Verify tags in the fetched HTML or checker output, not just on screen: templates can hide duplicate titles or headings invisible in the design.
Step 5: Check canonicals and indexing signals
Duplicates waste crawl attention and split signals. For each audited page:
- Find the canonical tag. A self-referencing canonical (pointing at the page's own preferred URL) is the normal, healthy case. A missing canonical is worth logging; a canonical pointing at a different page means this URL is asking to be treated as a copy — make sure that is intentional. The full rules are in Canonical Tags Explained.
- Check for
noindex. Anoindexin the meta robots tag or theX-Robots-Tagheader removes the page from results — correct on thank-you pages and staging sites, a disaster when a template applies it everywhere. - Check robots.txt — if there is one. A missing robots.txt is not a defect: without the file, every crawler may fetch every page, which is what most sites want. If the file exists, confirm it blocks no important sections and names your sitemap. Remember, robots.txt controls crawling, not indexing: a blocked page can still be indexed if other sites link to it.
Step 6: Check internal links, images, and the sitemap
Internal links tell crawlers which pages matter. During the audit:
- Click through from the homepage: every important page should be reachable within a few clicks, with no orphans — pages no internal link points to.
- Check that links point at final URLs, not redirecting ones — linking to a redirect rebuilds the chains you removed in Step 2.
- For images, confirm each has an
altattribute: descriptive for real images, empty (alt="") for decoration. - Fetch
/sitemap.xml, if the site has one. Every URL in it should return 200, be the canonical version, and be allowed by robots.txt. If a small site has no sitemap, log it as informational at most: search engines find small sites by following links, and a sitemap earns its keep as the site grows or crawl paths get complicated. An inaccurate sitemap is worse than none — the worked example's sitemap sent crawlers to 12 dead URLs. To build or rebuild one, follow How to Create an XML Sitemap.
Step 7: Prioritize, fix, and re-check
Sort findings by consequence: high severity first (fetch errors, a blocked core section, noindex on important pages, a sitemap full of dead URLs), then medium (redirect chains, missing descriptions and canonicals, HTTP serving a duplicate instead of redirecting), then low (titles overrunning the display guideline, missing social tags). A missing robots.txt never belongs on the list, and a missing sitemap on a small site is a note, not a task. Work through the list, then re-run the same checks, recording new results next to the old ones. An audit you cannot re-run is just an opinion.
Copyable audit checklist
- [ ] URL list built, with expected status and preferred form for each
- [ ] Final status code recorded for every URL (200 expected)
- [ ] Redirect count recorded; chains longer than one hop logged for fixing
- [ ] HTTP version redirects to HTTPS (no duplicate 200)
- [ ] Title present and unique; length judged by the display guideline (truncation is by pixel width, not characters)
- [ ] Meta description present and a sensible display fit (120–160 characters as a guideline, not a rule)
- [ ] Exactly one H1; heading order is logical
- [ ] Canonical tag present and self-referencing (or intentionally different)
- [ ] No accidental
noindexin meta robots orX-Robots-Tag - [ ] robots.txt, if present, blocks nothing important and names the sitemap (absence is not a fault)
- [ ] Sitemap, if present, returns 200 and lists only live, canonical, indexable URLs
- [ ] Internal links point at final URLs; no orphan pages
- [ ] Images have appropriate alt text
- [ ] Findings re-checked after fixes, with dates recorded
Troubleshooting: when the audit itself misleads
- The checker or
curlcannot fetch the page at all. A failed fetch is not automatically a finding. DNS and TLS failures can be local to your network, and CDNs and firewalls routinely refuse automated requests with a 403 or a challenge page while serving browsers normally; some content also varies by geography. Re-test in a browser, and from a second network if you can, before logging it as broken. - HTTP and HTTPS give different results. One may redirect while the other serves the page, or both may serve duplicates. Pick the canonical version, redirect the other to it, and audit the survivor — but record the discrepancy: it is itself a finding.
- A staging robots.txt (or
noindex) reached production. The classic accident: a stagingDisallow: /file, or a template-widenoindex, is deployed live, and a healthy site quietly disappears from results. Check robots.txt and the meta robots tags after every deployment, not just during audits. - Results change between runs. Pages get edited, redirects get added, and CDN caches serve stale copies, so two runs an hour apart can honestly disagree. Record the date and time of each run, and compare like with like before declaring a regression — or a fix.
Conclusion
An audit is a habit, not an event. The proof is this site's previous build: in a browser it looked finished, while the crawlable evidence — an empty homepage, a forbidden tools index, a sitemap of dead URLs — told the true story all along. Run the checks in order, record what you find, fix by consequence, and re-check after every significant change.
Frequently asked questions
Does a missing meta description hurt rankings?
No — it does not block indexing or directly lower rankings, and search engines can generate a snippet from page content instead. It still belongs on your fix list: your own description usually beats an improvised one.
Is a missing robots.txt or sitemap an error?
No. A missing robots.txt simply means crawlers may fetch everything — the normal default — and a missing sitemap on a small site is at most a minor note, because search engines find small sites by following links. Either file becomes a finding only when it exists and is wrong: a blocking robots.txt, or a sitemap listing dead URLs, as in the worked example.
Can I audit a site without access to its server or Search Console?
Yes. Everything in this guide uses publicly fetchable evidence: status codes, headers, page HTML, robots.txt, and the sitemap. Server logs and Search Console data add depth, but they are not required for the core audit.
About this guide
By the AtoZTools Editorial Team. Last reviewed: 24 October 2026.
Editorial review: second-pass AI review completed October 2026; human review pending client designation.
References
- Google Search Central, SEO Starter Guide — https://developers.google.com/search/docs/fundamentals/seo-starter-guide — Accessed 24 October 2026.
- Google Search Central, Build and submit a sitemap — https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap — Accessed 24 October 2026.
- Internet Engineering Task Force, RFC 9110: HTTP Semantics (status codes, Section 15) — https://www.rfc-editor.org/rfc/rfc9110.html — Accessed 24 October 2026.
- MDN Web Docs, HTTP response status codes — https://developer.mozilla.org/en-US/docs/Web/HTTP/Reference/Status — Accessed 24 October 2026.
Related reading: Robots.txt and Sitemap Toolkit, configure robots.txt, diagnosing indexing problems, SEO titles and meta descriptions, structured data with JSON-LD, topic clusters and internal links.